The case for Synchrony in Enterprise 5G deployment

Overlooking the vast waterways of Surma plains in the north eastern part of Bengal delta, I observed a natural phenomenon in my childhood that till date vivid in my mind. As migratory birds flock over the waterways during the twilight of dawn and dusk, they appear to maintain a natural symmetry of forming a sign wave across the distance horizon. The waves of flocks are seemingly phase aligned.

We rarely think about this naturally occurring phenomena when it comes to the design of network infrastructure, yet it is something de-facto in how communications devices work in a synchronicity. Whether a network is homogenous or heterogenous, imperatives of synchronicity cannot be overlooked, nor it can be ignored. Every device in a network from computers to routers, an inherent synchronization is in work by design thanks to the advent of oscillators for local reference and NTP for distributed synchrony. For many of us looking under the hood is not something we do often when it comes to designing the network. However, given the increased applications of time-sensitive transport in different industry verticals, synchronicity can no longer be assumed or overlooked. It is especially true for 5G deployments due to its common use of TDD spectrums in the Radio Access Network (RAN).

Why is Synchronicity important?

Today, an enterprise network is more hybrid, having a mix of homogeneous and heterogeneous applications that are distributed across the network. Let’s take a conventional distributed database system for example. Enterprise can no longer be able to afford having centralized coordination of stateful data scaling out within a centralized data center [1] where specific design assumptions are applied to control the network environment. Even in such circumstances common use of NTP based synchronization no longer serves the purpose of concurrency control. Moreover, enterprises are now on the verge of accepting the reality of edge and the challenges of heterogeneity that comes with it. 

Figure 1. Enterprise network slice with geo distributed database, edge processing and CBRS deployment.

Organizations are global today than ever before, and their operations are geographically distributed. Conventional distributed databases no longer serve the purpose of horizontal scalability, transactional consistency for geo distribution and geographically distributed data residency. The choice is a geo distributed database one that takes into context the complexities of time series data input at the edge, maintains data sovereignty compliance with data residency and transactional integrity [2] of geo-partitioned databases. With this geo distributed database requires a distributed sync plane that maintains highly precision traceable primary clock reference for end to end data-path. Some hyperscalers such as Google have addressed this issue of distributed synchrony with the “true time” API for their geo distributed database service “Cloud Spanner”. While enterprises can leap on solutions such as geo distributed cloud database services, there are numerous scenarios in which having resident geo distributed databases or hybrid solutions thereof are more beneficial. For the later, the importance of distributed synchrony cannot be ignored. Moreover, enterprises need distributed synchrony for many other applications e.g. CBRS and plant operations etc.

Synchrony for Private Enterprise 5G

  Delivering better cellular coverage and network mobility support to geographically distributed enterprise locations provide tremendous benefits to enterprises, from manufacturing to logistics and fleet operations. More of us are familiar with private LTE that has been increasingly penetrating enterprise networks over the last few years. Enterprise 5G a step ahead of private LTE delivering better bandwidth, reliability and inherent support for URLLC infrastructure. Furthermore, enterprise 5G can decide how to manage third-party traffic from operators or other service providers without disrupting its own traffic [3]. Interestingly 3GPP band 48 with a spectrum of 3.5GHz offers a great choice for enterprise 5G solutions. Known as CBRS (Citizen Band Radio Service), this new band offers open access to a 150MHz spectrum for use by enterprises. This service can be obtained by CBRS solutions providers who provide open access to 150MHz by using a scanning service known as SAS (Spectrum Access System) which protects against interference from higher priority users. CBRS uses TDD spectrum and thus requires high precision distributed time sync to deploy CBRS.

Figure 2. CBRS deployment as Enterprise 5G solution.

Some solutions offer a mix of LTE-A and 5G TDD spectrum allowing booth coverage and high bandwidth of up to 300 Mbps. A number of radio endpoints can be deployed in each floor of the corporate building enhancing multiservice transport capabilities over CBRS spectrum. In certain sectors (such as healthcare, hospitality, retail and manufacturing) CBRS is ideal and offers unmatched performance for mission critical applications. However, irrespective of CBRS deployment scenario distributed high precision synchronicity is a must.

Conclusion

Business users are increasingly adopting 5G for a myriad of use cases depending upon industry verticals: smart manufacturing, smart grid, healthcare, hospitality and retails. For this, high precision synchronization is inherent and must be considered beforehand prior to deployment. Moreover, today’s enterprise heterogeneous network cannot ignore the synchrony for many other applications from geo distributed databases to application of machine visions. Given the increasing need for high precision synchrony, a strategy for enterprise network synchronicity should include a clustered approach for secured resilient timing as well as geo distributed synchrony to support a myriad of geographically distributed applications. 

Reference

1.    Section, 2020. The Challenges of Distributed Databases at the Edge. Section.io.

2.    Lamb, C., 2021. The Guiding Principles for Cloud-scale, Geo-distributed Databases. DATABASE JOURNAL.

3.    Paolini, M., 2019. CBRS: Should the enterprise and venue owners care? Senza Fili. 

Incredible speed and the fat pipe: 400 Gigabits Ethernet

400Gigabits Ethernet

It is insanely fast, even a maverick will agree! And, it is equally fattish than the all known preceding transports technologies given that a 1 RU switch can now pack a whopping 12.8 Tbps bandwidth: get the picture?

Welcome to the world of terabit transport!

Target for massive aggregation in data center and service provider networks, 400 Gigabit Ethernet (400GbE) was approved as IEEE802.3bs standard on December 6, 2017. The 400GbE standardization marks a milestone towards 1 Tbps per port speed. With Chip vendors keeping up their game, 400GbE is now available in per port speed at 1 RU form factor and in chassis form factor. For a standard 32 ports 400 GbE 1 RU switch such as Delta’s Agema® AGC032, total bandwidth is whopping 12.8tbps. At chassis level, a combination of chips could provide service provider an option of upto 1 Pbps (Petabit per Second) system. To put in perspective, 1 Pbps is nearly thousand times bandwidth of 1 terabit system. That’s about breaking the barrier: like 5,000 two-hour-long HDTV videos in one second (Sverdlik, 2015).

Secrete ingredients of whopping speed

Sounds mind boggling! It should not be, advances in silicons made it possible for a combination of chips to support Petabits system. As for 400GbE Systems, the fundamental block of data interchange speed is 50Gig per second (50Gbps) run through 8 lanes to give a speed of 400GbE [50Gbits x 8] per port. This basic block of data interchange is known as SerDes (Serializer/Deserializer). In 100GbE, 4 lanes of 25Gbps SerDes are implemented to achieve 100GbE speed. Depending upon SerDes implementation, speed for each SerDes may varies, e.g. a 25G SerDes may have speed upto 26.56G. The diagram below depicts SerDes speed and lanes respectively for each type of link speed. For example, 10GbE uses a SerDes with single lane for 10G and 40G link speed uses 4 lanes of 10G SerDes to acheive 40GbE and so on. When 100G SerDes will be developed, such SerDes with 8 channels can achieve 800GbE link speed.

Figure 1. A diagrammatical representation of lanes and speed of SerDes that help achieve port speed of an Ethernet Switch.

The IEEE Standard

As stated earlier, IEEE802.3bs specifies requirements for 400Gig Ethernet implementation. The following diagram depicts typical vendor specific implementation of “400GbE layered architecture” of IEEE802.3bs. A semiconductor vendor may choose to implement IEEE802.3bs architecture in two chips or in a single chip [please refer diagram below]. The single chip implementations are most popular and silicon that offers such solution with additional software features are known as SoC (System on Chip). The sublayers specified in IEEE802.3bs architecture is drawn from original 802.3 std and subsequent revisions thereof for 1/10/100GbE. For those who are not familiar with sublayers of IEEE802.3 architecture, I am providing a brief herein below:

  • MAC (Medium Access Control): A sublayer for framing, addressing and error detection.
  • RS (Reconciliation Sublayer): It provides interfaces to Ethernet PHY.
  • PCS (Physical Coding Sublayer): The PCS is used for coding (64B/66B), lane distribution, EEE functions.
  • PMA (Physical Medium Attachment): This sublayer provides Serialization, clock and data recovery.
  • PMD (Physical Medium Dependent): It is a physical interface driver.
  • MDI (Medium Dependent Interface): It describes interface for both physical and electrical/topical from physical layer implementation to physical medium.

The sublayer of CDMII is not implemented and reserved for future use for which physical instantiation in not needed (D’Ambrosia, 2015).

Figure 2. A comparative outlook of IEEE802.3bs layered architecture of 400GbE and vendor specific implementation of 400GbE.

What’s in a box?

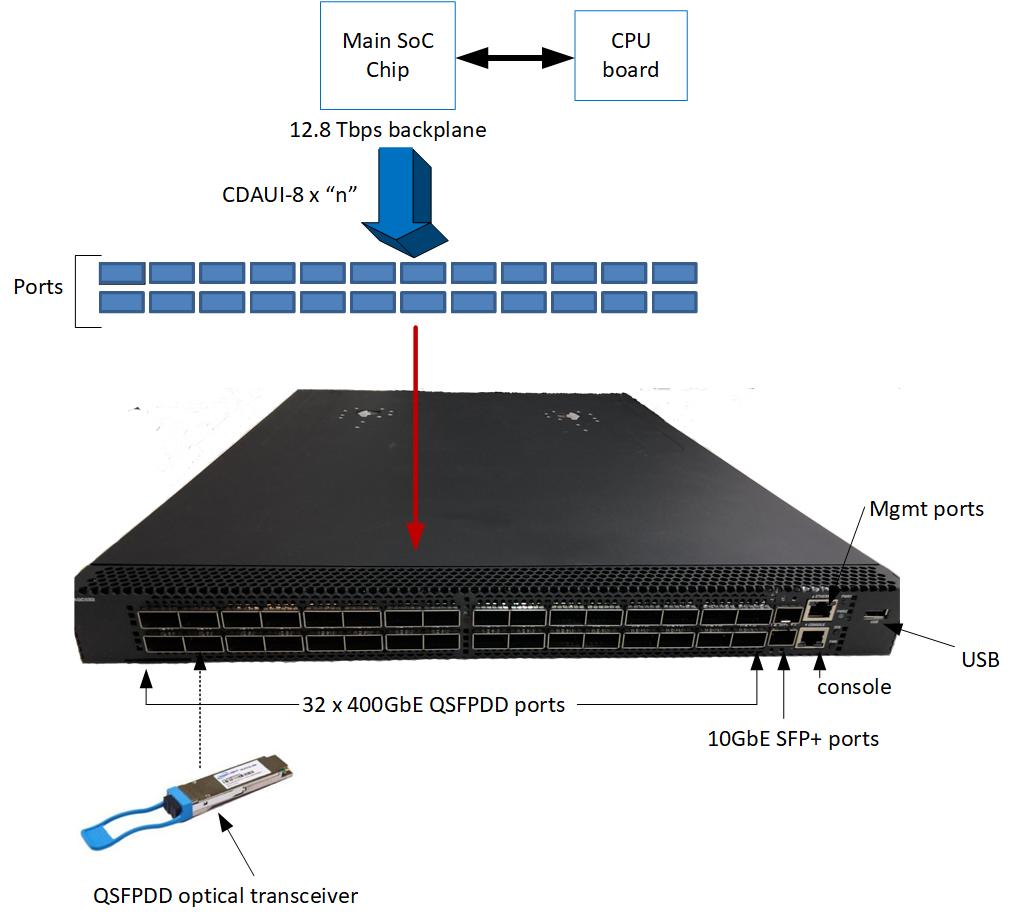
A typical SoC can packed up enough horse power to support more than 12 tbps of bandwidth for a 32 ports 1 RU switch. For example, Delta’s Agema® AGC032 supports upto 12.8tbps for 32 x 400GbE switch (please refer the figure below).

Figure 3. Agema® AGC032 12.8tbps 32 ports 400GbE whitebox switch.

Such design generally needs densely packed front panel ports and uses QSFP-DD form factor of optical transceivers for link level transport. The QSFP-DD expands QSFP/QSFP28 (an optical pluggable module commonly used in 40GbE and100GbE respectively) from four lanes electrical signals to eight lane signals. The QSFP-DD MSA group defines the specification for QSFP-DD. If you need further details on qsfp-dd, please download the specification from http://www.qsfp-dd.com/specification/ (QSFP-DD MSA, 2017). The QSFP-DD specification (QSFP-DD MSA, 2017) defines power classes for upto 14 Watts for single QSFP-DD module, however depending upon cage and module design power consumption may vary (please refer to table 5 and 6 of QSFP-DD specification for further details). Similar to QSFP-DD, other MSA (Multi-source Agreement) groups are also working on optical module specification for 400G and a list of them are given below. Please note, MSA is not a standard group rather an interest group comprised of optical transceiver vendors that often specifies form factor and electrical interface for optical modules.

MSA groups that are working on 400G optical modules:

The Interconnects

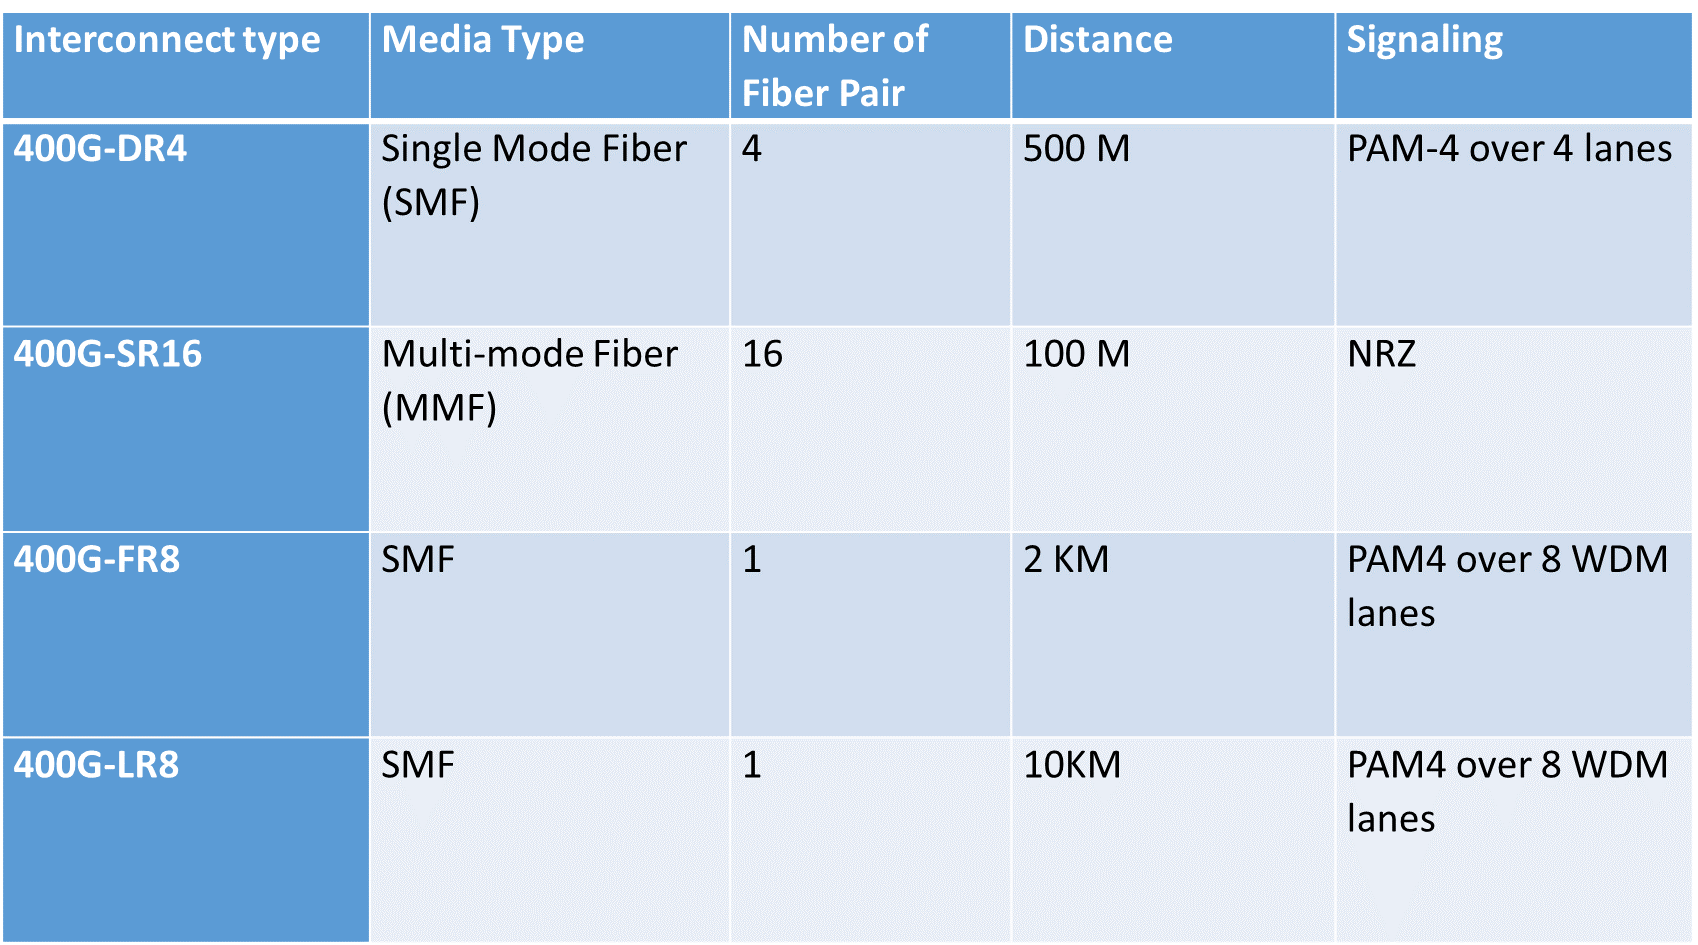
400GbE supports four different types of transceivers: 400G-DR4, 400G-SR16, 400G-FR8 and 400G-LR8. The following table depicts particulars for each type of interconnect.

Table 1. 400G Interconnect types, distance limit and signaling requirements.

Typical Deployment

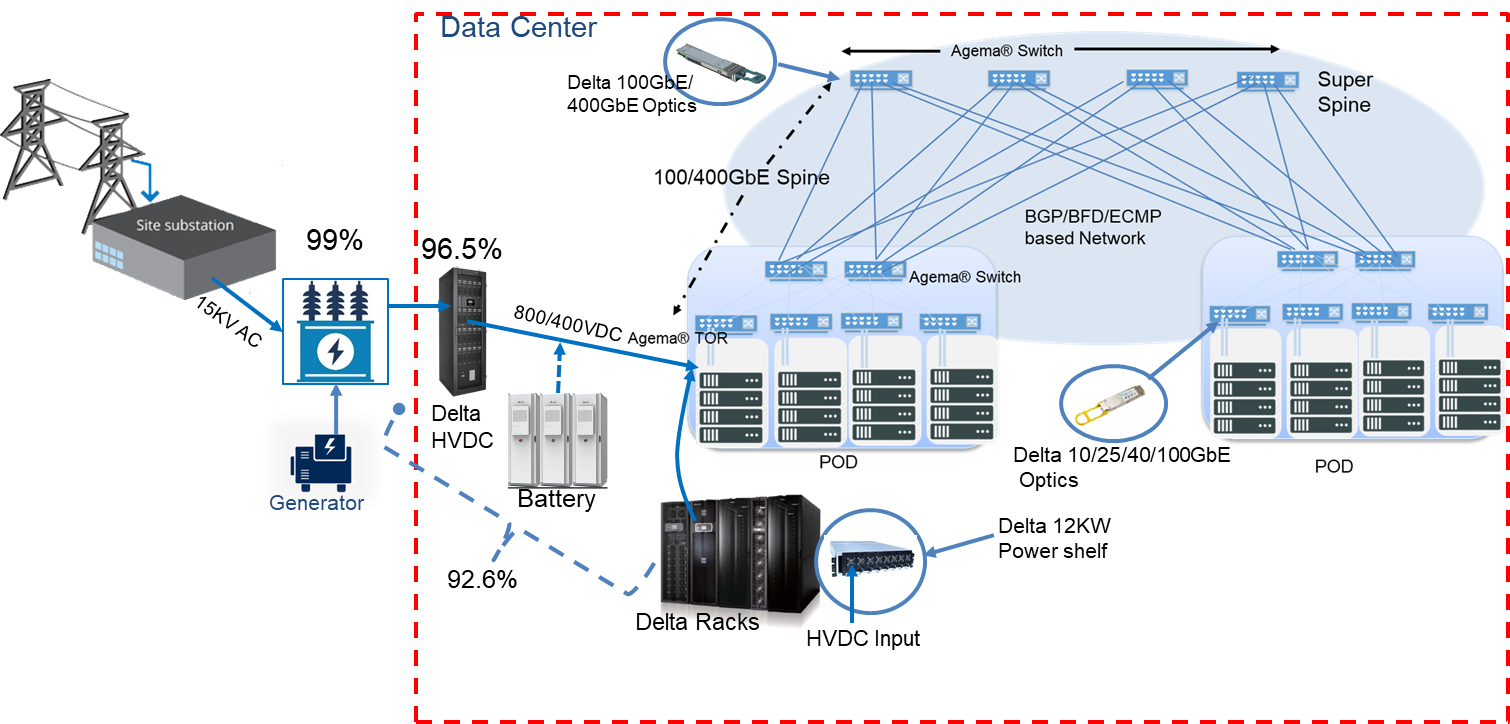
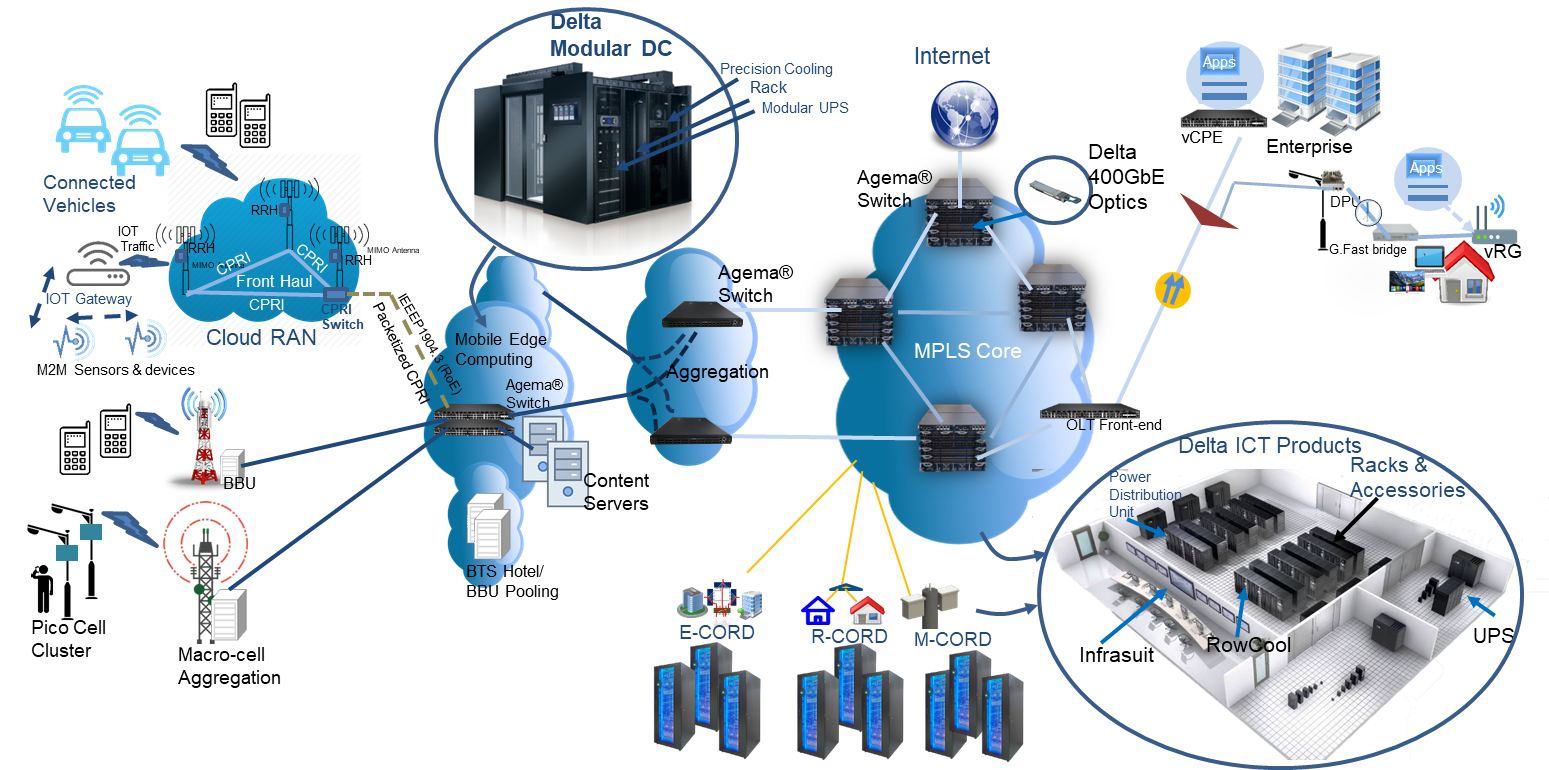
400G Ethernet Switches can be deployed in various configurations in Data Centers for Super Spine in a five folded Clos, Data Center Interconnect (DCI), Telecom Networks for aggregation and IXCs for transport peering etc. The following diagrams shows some typical deployments.

Figure 4. Typical deployment of 400G Whitebox Switch (e.g. Agema® AGC032) in super spine for Data Center Clos architecture.

Figure 5. Typical deployment of 400G in edge aggregation at telecom networks.

For distance over 10km, 400G deployment may need to use transponder and ROADM for better transport distribution on a dark fiber. Hopefully, distance limitation can be overcome with new optical transceivers for upto 100km in near future. However, transponders and ROADM will be necessary for distance beyond 100km and even for sharing single fiber at lower distance.

Conclusion

Welcome to the world of terabit transport. 400GbE is a great step towards terabit per port transport capabilities and given that whitebox switch is offering such possibilities at a better price, data centers and service providers are now able to build infrastructure for future payloads. Hence, addressing bandwidth demands would not be issue. With significant CAPEX and OEPX reduction offered by whitebox switches, service providers and hyperscale data center now can focus on more service offerings for what future holds.

Reference:

  1. Sverdlik, Y. 2015. Custom Google Data Center Network Pushes 1 Petabit Per Second. DataCenter Knwloedge. Avilable online at http://www.datacenterknowledge.com/archives/2015/06/18/custom-google-data-center-network-pushes-1-petabit-per-second
  2. D’Ambrosia, 2015. IEEE P802.3bs Baseline Summary: Post July 2015 Plenary Summary. Available online at http://www.ieee802.org/3/bs/baseline_3bs_0715.pdf .
  3. QSFP-DD MSA, 2017. QSFP-DD Hardware Specification for QSFP DOUBLE DENSITY 8X PLUGGABLE TRANSCEIVER. Available at http://www.qsfp-dd.com/wp-content/uploads/2017/09/QSFP-DD-Hardware-rev3p0.pdf

Facts behind the Myth of Whitebox Open Networking: A Reality Check

I begin with an assumption that you are somewhat familiar with “whitebox” term as it relates to networking gears and cognizant of its trend. For those needing a brush up, please read my earlier article https://www.linkedin.com/pulse/bare-metalwhite-box-solutions-open-hyperscale-data-center-chowdhury/ .

The term “whitebox” and “open networking” to some extent synonymous, both innately suggest networking gears that are “open” meaning adheres to “open” standards and ecosystems. The former is a byproduct of open networking concept and refers to the disaggregation model in which hardware and software are separated. This decoupling of hardware and software created opportunities for a software ecosystem to flourish: well, almost!

As with any technologies advents, early days are little bumpy. It is no different for whitebox and open networking ecosystems. There are few constraints but it has come long way since its introduction in 2011. Yet, some are cautious and doubtful of its reliability: perhaps confused by choices, constraints and complexities.

In this article, I will simplify and explain fact behind the myth of “whitebox”. This article is educational in nature and intended to help readership make right decision choosing whitebox in their network transformation.

 Making the right Choice

Let’s be candid! Choices are always good if we are prudent. During my presentation at Amsterdam OCP summit, someone asked me a question referring to the often confusing software ecosystems and choices thereof; as to what method one can take to make right choice for hardware and software?

Responding to this question outright in few sentences may be difficult but the method of whitebox selection could be simple: first, determine your network transformation needs and develop a checklist. It should include mandatory, good to have and nice to have feature lists. Secondly, match this checklist against hardware and software features of given whitebox solutions.

Figure 1. Whitebox product choices.

In figure 1, I depicted a diagrammatical representation of various choices available in a given hardware: herein, Agema products from Delta (http://www.agemasystems.com ). It shows four different choices for customers: bare metal (1), whitebox (2), bare metal with open source ONL/ONLP (3) and bare metal with OFDPA (4). If you do not have software resources and not planning to have experimental undertaking, please stick with whitebox. The “baremetal” switch is generally good for NOS (Network Operating Systems) vendors those who provide protocol stack software solutions e.g. IPV4, BGP, MPLS etc. If you have source code from particular NOS vendor and like to qualify this on a hardware platform go with bare metal. Those who are more incline towards experimental undertaking may go for Opensource route: 3 & 4 (refer to figure 1). The bare metal switch with support for ONL (Open Network Linux) is ideal for those who likes to work with ONL ecosystems. Please visit https://opennetlinux.org/ for more details. The OFDPA (Open Flow Data Plane Abstraction) option is good for people who prefers decoupling of data plane and control plane. This software is a contribution from Broadcom® and may not be fully supported in some of their silicons. Please visit https://github.com/Broadcom-Switch/of-dpa for further details and consult with hardware vendors for specific platform qualification in OFDPA.

 Choosing the Right Hardware (Networking Gears)

One thing you can be sure of that hardware are stable and reliable if you are buying from the vendor known for quality products. The same goes for software as well. More importantly, networking hardware that are available in whitebox disaggregation model now offer some of the “state of the art” silicons. To some extents, these hardware are more advanced than those available from typical networking vendors. For example, you may now able to purchase 100GbE platform that includes programmable chips. Not that it is important for your consideration when comes to traditional network transformation but those interested in experimental use of HW level APIs may find it tempting. Additionally, whitebox networking gears also offer performance and scalability choices.

Let consider the diagram below: the figure depicts choices of whitebox hardware from 1GbE to 30Tbps.

Figure 2. Whitebox Networking hardware choices.

Products are now available in standalone and chassis format. More importantly, some of these networking gears are versatile depending upon NOS availability. For example, you could use profile based deployments of a “Top-of-Rack” switch in many network scenarios including data centers and Service provider networks with ability to perform traffic engineering if so is desired. However, there is a caveat to it, not all hardware capabilities are utilized by NOS vendors. Hence, be prudent with your selection.

Networking Software Choices

The term “NOS” (Network Operating Systems) refers to networking software solutions that offers many networking protocols and application. Some NOS are more generic type having more emphasis on traditional networking protocols while others are focused on flow based or API based software solutions. Being prudent of choosing a NOS is thus important: if you are confused, ask respective hardware vendor as to which NOS best suits their platform. For example, if you are looking for a platform that should support let’s say 1 Million IPV4 route, ensure that the hardware are consideration comes with TCAMs and NOS vendor are capable of supporting the routes without performance compromise. Similarly, if you are having microburst scenarios in your data center and are looking for ways to minimize application performance issues, you may need deep buffer switch. The same goes for service providers. Therefore, understanding your networking needs andt jotting them down may help you make the right selection. Always, keep your mandatory checklist ready and use it as reference to match against hardware and software capabilities.

If you are not considering to decouple the forwarding (e.g. packet forwarding) and control plane (e.g. flow controls and/or flow based forwarding decisions), stick with traditional protocol suits. This is not to suggest that you do not need APIs/protocols for programmability and easier provisioning. You definitely do, but ensure what benefit it derives. I suggest that you always look for ZTP (Zero Touch Provisioning) capabilities in software irrespective of which NOS you choose. The ZTP will help you provision many switches at once reducing time and overhead cost associated with manpower.

 Figure 3. Network Operating System (NOS).

In the figure above shows typical NOS availability in a given whtiebox platform but there are more vendors available than those depicted above. Some are startups while others are well-known networking giant. Best way to find out is to contact respective hardware vendor.

Building the Network

Let’s be real! Transforming networks begins with few essentials: CAPEX/OPEX, Bandwidth consideration and business problem you are trying to solve. First, clear your mind of buzzwords, go to basics. Let’s consider you are building a data center network infrastructure or augmenting thereof. The important question is what fundamental architecture you are following and protocol suits you are looking for. Let’s say, you are building the data center network based on BGP and wanted to keep each cluster separated. I am depicting a typical setup considering the above deployment scenarios in figure 4 below. The physical network setup is based on spine/leaf architecture (known as “clos” named after Charles Clos). You may able to redesign such architecture to a five-stage folded clos to accommodate future demand.

The diagram shows Compute, Storage and Machine Learning Clusters are separated.  It so done to help you easily visualize the product needs in each area. For example, you may be planning to use separate switch for WAN and DCI leaving DC setup isolated from abnormalities of WAN or DCI routers.

Figure 4. Data center Spine/Leaf Architecture.

Similarly, you may want to keep your machine learning cluster in separate set of deep buffer switches minimizing application performance degradation due to micro burst. Whatever the network transformation decision you make, please ensure that you are choosing right networking gears considering specific deployment scenarios. As such, you cannot go wrong with your selection of whitebox solutions.

Same goes other network scenarios, whether service provider and/or enterprise.

The possibilities

I have thus far kept this article focused on traditional network transformation without referring to the possibilities of programmability, service orientation and artificial intelligence (AI) use cases in network transformation. While these discrete technological advents are having different triggers and origins, whitebox are making it easier to realize such technological bonanza. This can be a forward looking statement but such assertion is not without basis. For example, Open Networking paved the way for whitebox to be realized and at the same time it created the possibility of network programmability. Since whitebox products support open standards/ecosystems and are affordable, many researchers and startups are working to bring the programmability, service orientation and AI to networks. Considering such developments in the marketplace, I have created a timeline and presented herein below. The diagram depicts how each technological advents are connected and potential timeline for each advent to be realized.

Figure 5. Whitebox to cognitive networks timeline.

For example, Open Networking model created whitebox and helped developed software ecosystems. Such works made it easier to realize programmability and decoupling of forwarding/control plane (SDN) in whitebox platforms. Overtime, the ensuing software ecosystems and works thereof paved the way for further development works towards intent-based Network. This service oriented networking concept is still premature and the works are piecemeal at best, nonetheless, it is a near term possibility.

Similarly, Self-organized networks and Cognitive networks are some of the other new possibilities that may come to the fore by 2020. One potential is that Whitebox software ecosystem may soon offer deep learning agent at switches and AI engine at controller making the network more state aware. Hence, possibilities are endless with open systems though limitation may plague some deployment if end user is not careful. The bottom-line, if an end-user is prudent in their selection of whitebox, it will offer great potential in their network transformation.